Generative AI & Knowledge Systems
AI RAG Platform
What if the documentation could answer back?
AI RAG Platform
2024
TypeScript · Node.js · Vector DB · OpenAI API · Fastify
The idea behind the build.
Static documentation and company knowledge bases are hard to navigate. Standard LLMs hallucinate or lack private organizational context. Teams need a dependable way to ingest unstructured docs, retrieve relevant organizational context, and seamlessly embed this intelligence into external websites or apps.
What I brought to it.
Architect & Lead Builder. Designed the ingestion and chunking pipeline, configured vector storage and hybrid retrieval scoring, implemented prompt guardrails, and built the rate-limited public API layer.
The system
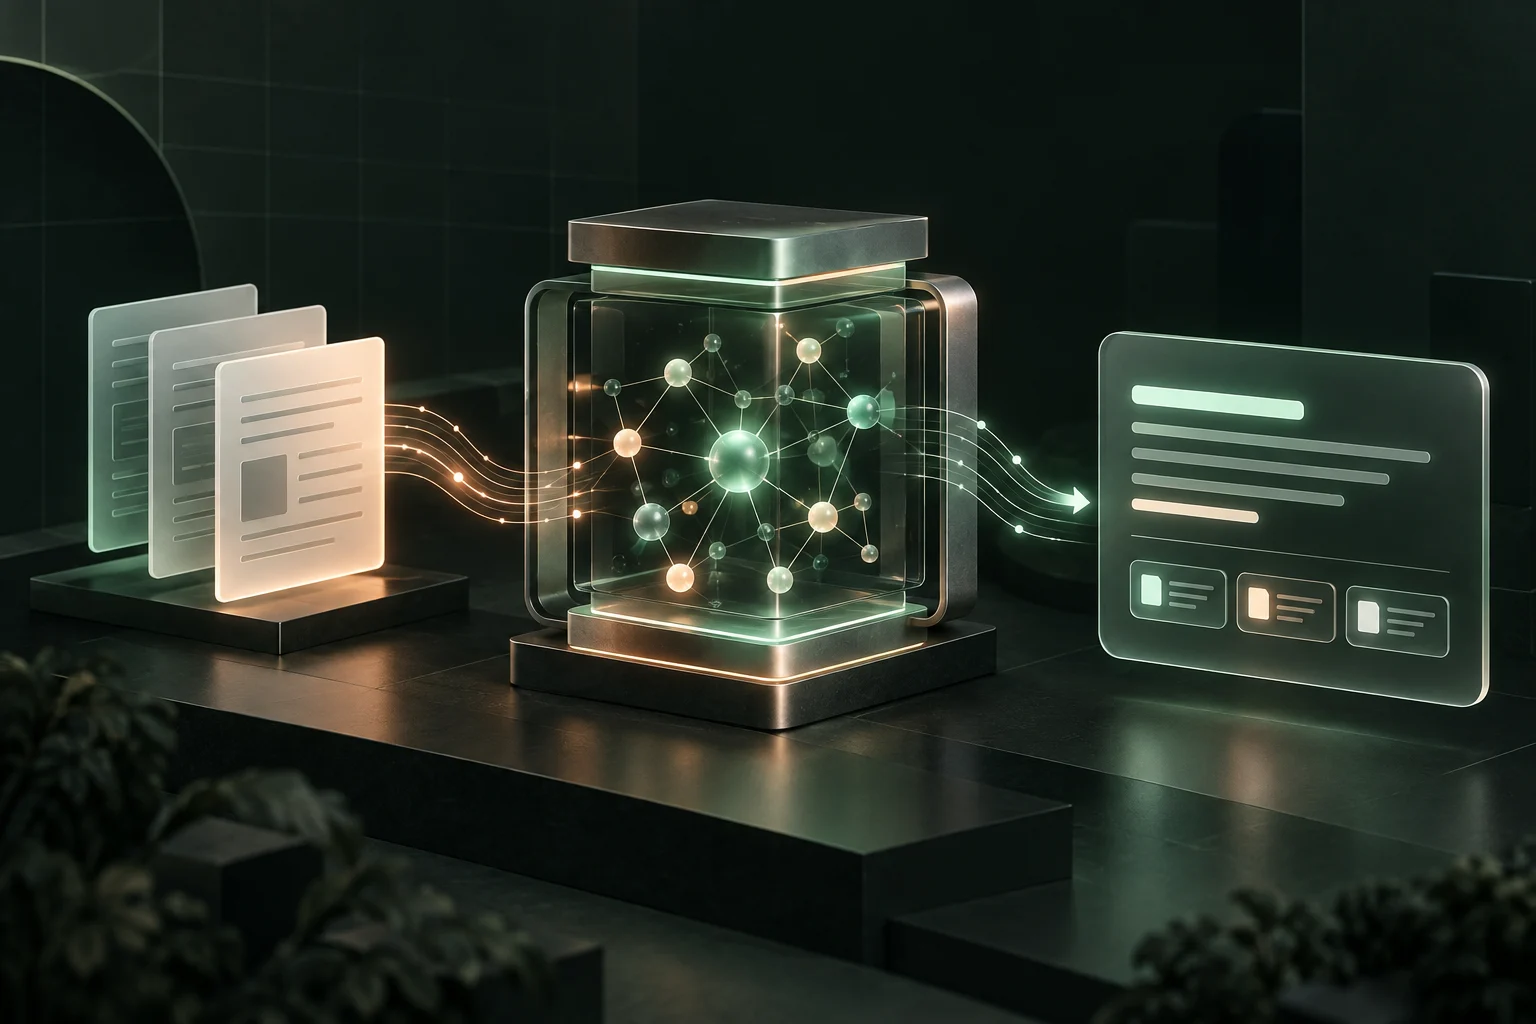
An end-to-end document intelligence platform that parses PDFs, markdown, and text, applies semantic chunking, generates high-dimensional embeddings, stores vectors for hybrid similarity search, and augments LLM prompts with strict citations—packaged with a developer-friendly public REST API.
The interesting challenge
Chunking strategy and retrieval noise. If chunks are too small, context is lost; if too big, the context window fills with irrelevant text. Balancing semantic boundary splitting with metadata preservation so the LLM cites exact clauses.
Under the hood
- Document parser supporting PDF, TXT, DOCX, and Markdown
- Semantic chunker with overlapping sliding windows and section hierarchy
- Vector search integration using high-dimensional embeddings with cosine similarity
- Context-stitching engine injecting verified snippets into structured prompts
- Public developer API with API key authentication, rate limits, and usage analytics
What shipped
- Robust single-tenant document ingestion pipeline with status tracking
- Semantic vector retrieval engine with citation links
- Public REST API with interactive documentation for third-party embeds
- Admin telemetry dashboard tracking token usage, latency, and query accuracy